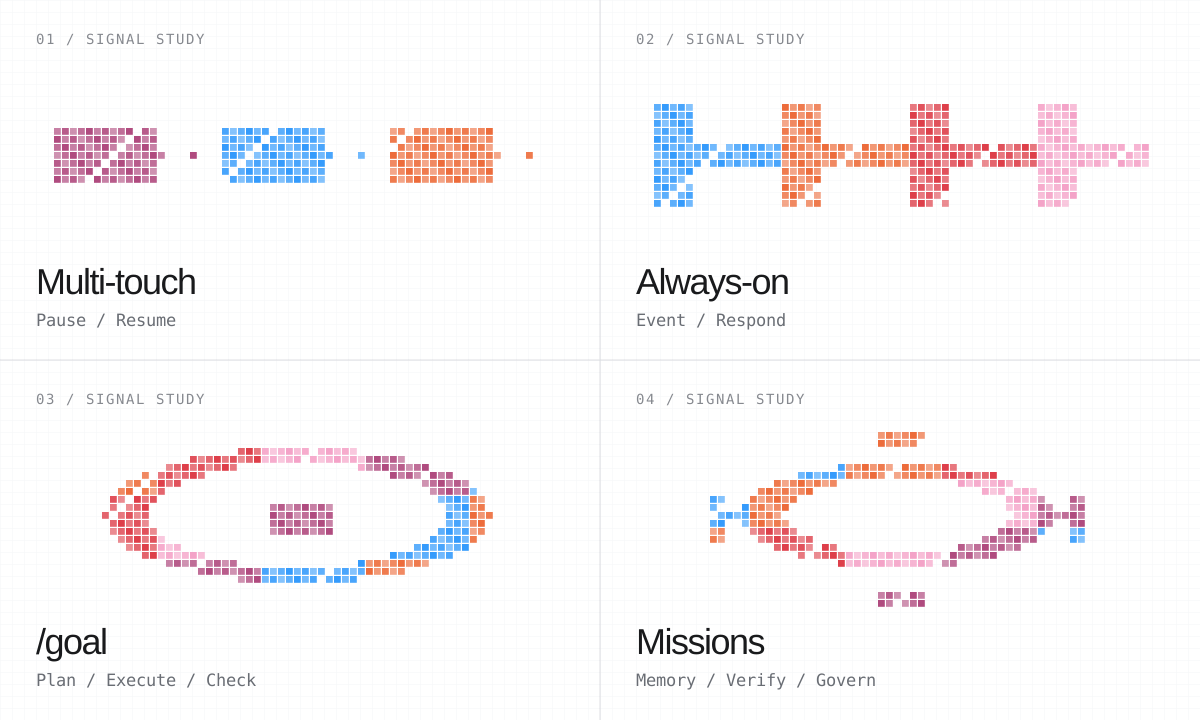
As we enter another hype cycle, what actually is a "long horizon" agent?
As of August 2026, there are four patterns.
01 / Multi-touch agents
Multi-touch is the ability to start, stop, and resume while executing over a single case.
As an example, a sales multi-touch agent will message a potential customer and shut down. Once the customer responds, the agent wakes up with all the context from previous touches to continue the conversation, sends another message, and sleeps again until the next turn.
These agents pause and resume to handle full sequences autonomously.
Examples include recruiting, customer onboarding, and insurance claim processing.
02 / Always-on agents
These agents are alive 24/7. This doesn't necessarily mean running continuously. They can respond to events or run on a schedule. The key difference is that, unlike multi-touch, every agent session begins with only the new event context.
Common use cases revolve around fixing bugs as they appear in your logs, calling an expert for help, and continuously generating code.
Examples include AI-native observability, SRE, and CI/CD.
03 / /goal
A /goal agent starts a loop with a stop condition.
For example: "migrate this code to Rust while passing all unit tests." The agent keeps rewriting code and running tests until they all pass.
The goal is repeatedly decomposed into bite-sized tasks for subagents to execute in parallel. Planner agents continuously orchestrate subagents to pursue different lines of reasoning and make progress.
Examples include migrating a codebase to Rust, booking a flight to Mexico, and clearing out an inbox.
04 / Missions
A mission is a lot like /goal, in that the agent runs in a loop that doesn't stop until a certain goal is met. Except for one difference: custom problem-solving components.
Imagine early access to a frontier model and $27 million in allocated budget for tokens. How do you get the most out of it?
A good mission wraps the model in a problem-specific environment. More context and a longer run alone won't provide:
- The ability to persist memory to external artifacts so the context window never gets overloaded. Facts, decisions, failed attempts, and evidence are all kept for later.
- Verifiers for what can be checked: tests, delivery confirmations, simulations, and human review.
- Guardrails around access, budgets, escalation paths, and rollbacks.
The memory, evidence, and guardrails are all externalized out of the agent's control. This hinders its ability to cheat, blunder, or forget.
Long-horizon agent missions are best suited for high-complexity, high-judgment, and high-value problems.
Examples include disproving a century-old math conjecture, cybersecurity, and autonomous R&D.
DeepTrain builds long-horizon agents for complex work. Talk to us about a problem.